Is Opus 5.5 nerfed? Thinking patterns changed on November 3
Posted by rzk 17 hours ago
Comments
Comment by PhunkyPhil 6 hours ago
Every time a new model drops it feels wildly powerful, then regresses to some sort of generic SOTA level we've been used to over the last 6 months.
I remember my first coding prompt with, I think it was sonnet 4.6, on a fresh account and it was shocking how much it successfully did off a single prompt - I haven't found that with any other model at any other time and I suspect it was because they put me at the top of the priority list to get a "wow" reaction.
Regression after a release is pretty well-agreed upon, but I'm wondering if they secretly have a huge amount in the tank they aren't releasing. Either as a card to play in the future, or because they can't keep up with demand. I've heard anecdotes of people working in these companies saying that the public models aren't even close to their actual capabilities... Anyone have any opinion on this?
Comment by nickalaso 5 hours ago
I worked recently for a German megacorp, for whatever reason they gave us unlimited access to a bunch of models, up to sonnet 4.5/Gpt o1 etc, so not the best or latest models. And no agentic tools.
So I built a custom Claude Code clone because they exposed the api from their custom 'LLM Chat' clone in the client and accepted my user credentials for access.
Essentially a frankenstein AI harness using various models for their strengths, including using the OpenAI best model for memory context consolidation and compaction + Sonnet as orchestrator, etc. I was able to spawn 20+ agents to do my work and basically automate my entire job at that corp. I think my internal bill was something like 5k euros per month and I was being careful to not abuse it...
It was better than the best you could get from claude at the time (about a year ago now I think), in terms of task performance completion.
So imagine what someone with essentially infinite spend can do with endless fable agents. AKA US government and Anthropic internal.
Comment by aucisson_masque 1 hour ago
Not a great plan
Comment by nickalaso 1 hour ago
Comment by mrinterweb 4 hours ago
If I order a 16oz beer and get a 12oz pour, I'm going to call it out.
Comment by rmetzler 2 hours ago
Comment by monkeydust 5 hours ago
Comment by pydry 4 hours ago
Comment by Y_Y 2 hours ago
Comment by SpicyLemonZest 1 hour ago
Comment by youngprogrammer 4 hours ago
Comment by jpadkins 1 hour ago
Comment by abustamam 4 hours ago
2. Google doesn't pretend that its algorithm has certain capabilities while serving the user a nerfed version
Comment by radlad 2 hours ago
Comment by tortasaur 1 hour ago
Comment by giancarlostoro 3 hours ago
I'll gladly sign up to be a "Experimental Settings" beta tester (with knobs of how extreme I want to go) for a slight discount (or just bill me the same, just gift me a reset every week? idk whatever).
Doing A/B testing in prod on a frontier model that could really mess with the users in really bad ways is a bad idea.
Comment by augment_me 2 hours ago
Comment by giancarlostoro 2 hours ago
Comment by augment_me 2 hours ago
Comment by giancarlostoro 20 minutes ago
Like Windows 8?
Comment by NewsaHackO 3 hours ago
Comment by nickalaso 3 hours ago
Comment by makmanalp 1 hour ago
Comment by onlyrealcuzzo 5 hours ago
Opus 5.5 was significantly crushing every task I gave it for quite some time.
Suddenly, it starts making the type of mistakes that even Sol 5.6 would not make. It became noticeably worse than Astra.
I've grown so completely tired of the labs changing the quality of the model out from under our feet that I CANNOT wait until there's viable alternatives at the frontier level.
I will gladly forgo the best available power for consistency - and I see that coming soon (hopefully with Qwen 4 or shortly after).
DeepSeek v4.1 Flash is not even remotely in the same league as an un-nerfed Astra or Opus 5.5 - despite what microbenchmarks may claim.
It's a great model, especially for the cost - but there's a huge difference.
Comment by vadansky 5 hours ago
Edit: Just to add some more ridiculousness:
> The last squash stalled because it opened an editor to merge descriptions. I've stopped it. Checking what landed:
I was using jj with Claude for a while now, suddenly it forgot how to squash? It also started doing that stupid thing where it edits files through python scripts so I don't see the diff during manual mode. This is like 3.5 levels of stupid.
Comment by ariwilson 4 hours ago
Comment by lukeschlather 37 minutes ago
I would also agree that 5.5 feels dumber the past week. More weird logical problems. it's not as dumb as 5.1 or 4.8 but it feels like it regressed.
Comment by stefanfisk 5 hours ago
Comment by pier25 3 hours ago
I suspect it's rather a simple matter of cost.
Comment by tibbon 4 hours ago
Comment by RobotToaster 5 hours ago
Comment by pc86 5 hours ago
If you're selling model capabilities for money, and you change the mobile capabilities, not changing the model designator (name and/or version number) is fraud, full stop.
Comment by woodson 5 hours ago
Comment by _blk 5 hours ago
Comment by pc86 3 hours ago
And yes, if you're doing engineering that violates the law, you should be fearful of doing. That's kind of the point of punishing criminals.
Comment by woodson 3 hours ago
https://www.justice.gov/archives/opa/pr/volkswagen-engineer-...
Comment by FireBeyond 4 hours ago
Unlike here where the "phantom bank accounts" fraud was successfully pinned on tellers and branch managers who were all "independently" just trying to meet management goals...
Comment by Obscurity4340 5 hours ago
Comment by WarmWash 5 hours ago
Comment by dofm 4 hours ago
Is this 2026's "my macbook feels 'snappy' when I update it", though? (That is to say, not really much in evidence)
House of El covered this in her latest video incidentally.
Comment by _doctor_love 5 hours ago
Oh good Lord, they stir the pots constantly. Anthropic is hella naughty about this. Someone else on HN said it well, Anthropic has too much of a "researcher" mindset. You cant experiment on human populations tool use the same way you run AI/ML experiments.
I want a stable tool that works consistently, not a hammer that changes mid-swing (credit Mario Zechner for this analogy).
Comment by brainwad 5 hours ago
Google and Facebook have proven otherwise. Unless you are very, very lucky you are always part of multiple running experiments on their products, and nobody really cares.
Comment by _blk 5 hours ago
Comment by espeed 4 hours ago
Comment by 93po 5 hours ago
Comment by BeFlatXIII 2 hours ago
This isn't new to the current LLM bubble. Grammarly has been like this for 10 years.
Comment by CamperBob2 5 hours ago
I don't know who they think they're fooling.
Edit: Fable 5.2, whatever. There you go.
Comment by j45 4 hours ago
Comment by PaulKeeble 9 hours ago
It is something I also appreciate with some of the other labs like deepseek who publish the checkpoint they are running on and still sell you the old one for a period of time as well.
Its obnoxiously anticonsumer to be constantly chopping and changing what a model represents on customers who are paying them an awful lot more to be on the frontier models.
Comment by serial_dev 6 hours ago
Comment by throwawayffffas 30 minutes ago
Qwen 3.8 is useful and honestly impressive but it's far from slightly worse.
For slightly worse you need something like Kimi K3.1 or glm 5.3
Comment by make3 1 hour ago
Comment by aerhardt 6 hours ago
Comment by CryptoBanker 6 hours ago
Comment by CamperBob2 5 hours ago
Comment by xiaoyu2006 5 hours ago
Comment by nannal 5 hours ago
Comment by montroser 5 hours ago
Comment by kylehotchkiss 7 hours ago
Better tooling/reporting to demonstrate model degradation is needed though.
Comment by cyanydeez 7 hours ago
Comment by p00ki3 6 hours ago
Am talking about low level Linux kernel interfacing stuff, my own Google Opal like UI generator...still rough but it's machine state to bang into shape not a bridge. It works but needs the refinement common to early development
Imo due to recent job trope developments a lot of devs expect a git repo that feels like a 3-ring binder with their senior thesis and such tucked within
Local models inability to one shot such is being used as cope. Imo these models are more capable than we want to believe
This all reminds of 20 years ago when sysadmins refused to acknowledge the cloud would take off due to privacy concerns of businesses
Look how that went
Data center needs are inflated to try and capture all the business but future devices capable of optimized battery/telemetry aware local inference would satisfy most people
The data centers serve 3 groups; SaaS workers, data center landlords/CEO/shareholders, politicians being paid off by data center landlords/shareholders
The other billions on the planet do not directly benefit as much. Merely as a side effect of trickle down
Comment by nickalaso 5 hours ago
Of course the Sota models on the same custom harness got to about 99%, but I'm amazed at the performance of such a tiny public free model running on my 3080 laptop gpu. If it was actually finetuned for said task I imagine it could get to 90%+ completion.
Comment by cyanydeez 3 hours ago
Of course, any given person might want their own navier-tokes agent swarm of a solution, but the number times you want a bot to fill out a resume rather than solve a millenium problem is absurdly lopsided.
So it's just kinda, ok guys, are you going to just try to hold us hostage with your magicaly super-duper-intelligence, or are you going to admit that having great models means humanity gets a few smart people to be even more useful for whatever they're working on.
The rest of us arn't going to even see that future to begin with, because food, it's not about how much food humanity grows; it's how it's distributed. Unless this AI stuff solves a problem _no one_ has solved for food, it's just going to be another power chair to fight about who gets to sit there, who has the right to sit there, or like I suggest, it's just a utility thats to be managed by the same governance all other utilties do and has the same problem thereof.
So like, boring stuff; not p(dooom)
Comment by nickalaso 3 hours ago
IMO these models are best at non-coding tasks. They of course have to use a computer, but from CAD generation, 3d Modeling, emails, legal and academic analysis, etc. these models are incredibly capable, and we are going to see a massive shift in the entire job market due to this, and ironically I suspect one of if not the most protected career as a result of this massive upcoming buildout will actually be software engineers.
Comment by p00ki3 1 hour ago
Am ultimately whittling everything down to Linux kernel + inference + data model so far captured from my current OS use.
Am ready to be done with syntactic programming of the machine. Rather than label the filesystem with context I can label entities in the viewport and those entities can happen to look like word processors not just video game characters.
An basically making a Blender-clone designed to browse and edit models that replaces the usual desktop metaphor.
Then I can noodle the virtual geometry, label it and understand under the hood its just a function factory mutating geometry of memory address truth table and display truth table.
The last gasp/push to rid ourselves of OOP is upon us; code objects of all kinds gonna be dead sooner than later.
Not sure I agree then software engineers will be insulated when everyone can do state management through visual edits. Maybe visual design work will still be a thing; the how to get machine into desired state is most certainly not going to be with visual syntax structure fir much longer
Comment by AmazingTurtle 5 hours ago
Comment by benatkin 4 hours ago
Comment by ianberdin 2 hours ago
Max, streamed (128K cap): 128,000 tokens, $2.56, empty file, in September and today.
Max, Batch API (300K): 255,957 tokens for $2.56 in September, 243,707 for $2.44 today. The two drawings: https://playcode.io/marketing/assets/static/claude-opus-5-5-... and https://playcode.io/marketing/assets/static/claude-opus-5-5-...
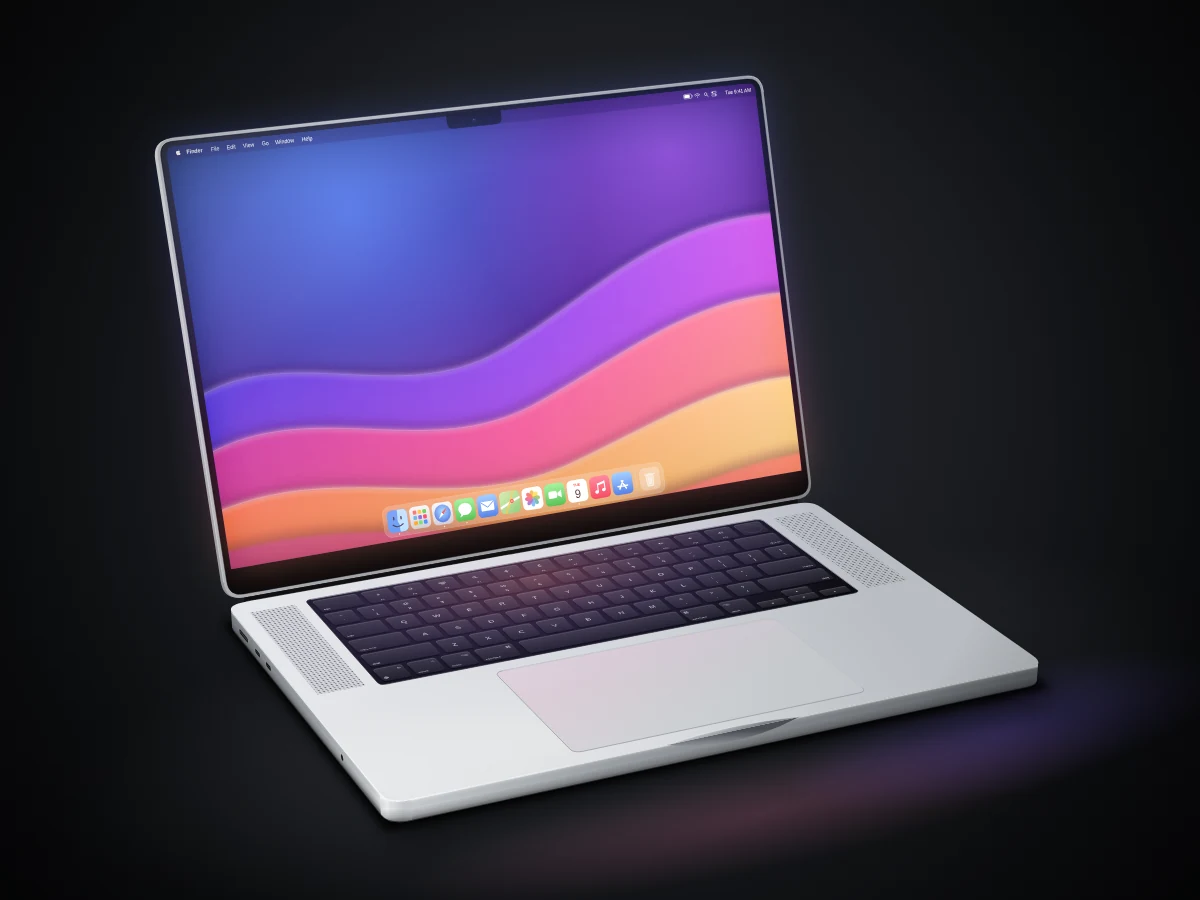
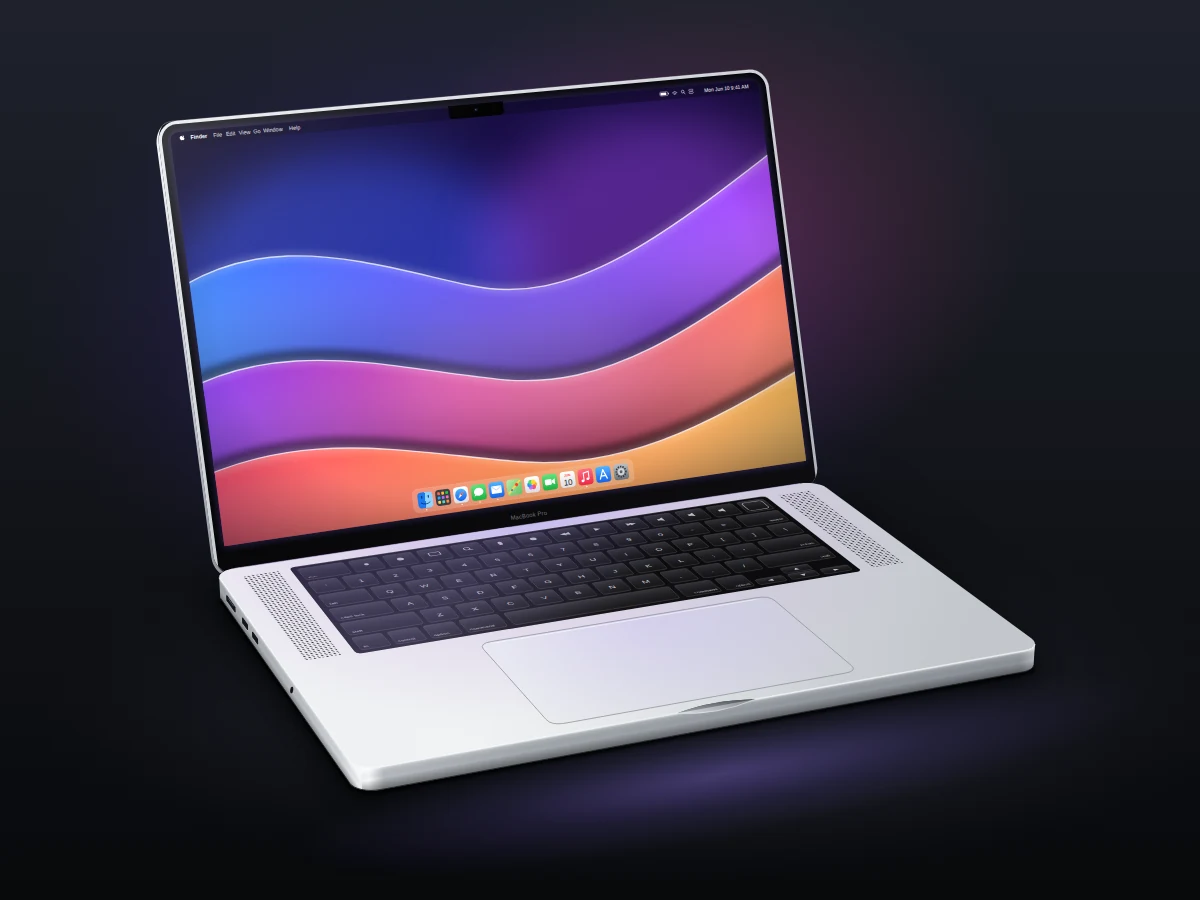
Xhigh: 86,096 tokens for $1.72 in September, 107,333 for $2.15 today.
The Batch API bills half price. Max ran out of the 128K ceiling again, to the token. Given 300K, it drew the same kind of laptop with 5% fewer tokens. Xhigh used 25% more and drew the same kind of laptop. That's inside the noise: 17 identical calls at high ranged from 17,757 to 59,705 tokens.
The model is still the best of everything we've tried. Most likely the next best would be Fable 5.2. But we don't like Fable because essentially the result is the same, just the price is higher. Its medium and high are close to what Opus 5.5 Max had, but the price is higher.
(I run Playcode, an AI app builder. We benchmark every model before we add it.)
Comment by martini333 1 hour ago
Comment by tossstone 1 hour ago
Comment by handoflixue 1 hour ago
Comment by losvedir 9 hours ago
The only one I'm familiar with testing Opus 5.5 specifically over time is https://github.com/ninjahawk/livenerf and it's not showing anything.
Comment by seizethecheese 5 hours ago
If you calculate Elo only before 11/3 and compare to only after 11/3, the Elo is 52 points lower after. Unfortunately we are still in beta so this isn’t conclusive (confidence interval of -160 to +40).
If we do this calculation on all our models, Opus 5.5 is first in apparent drop. (Again, not definitive, but supports the conclusion.
Comment by kingstnap 5 hours ago
Firstly, there is a lot of A/B testing. You would likely need at least 10 or 20 accounts to catch these random tests.
Secondly, the labs obviously run GPQA and MMLU like livenerf does and watch for their own regressions before doing A/B tests. These benchmarks are statistically the thing already being filtered out. You need tasks out of distribution. Ideally ones in distribution with the stuff they particularly frequently change (like safety or copywrite adjacent tasks).
These harnesses, and hidden system prompts, do get screwed with quite a lot in my experience. The models are actually remarkably consistent via API but there are tons of stealth system prompt and harness changes that lobotomize these models all the time.
Like despite being stochastic, try asking Luna to generate you a video game pitch via the API 100 times. It's almost always the same thing about lighthouses for some reason. That's actually why I made a CLI entropy generator project.
Comment by nsingh2 8 hours ago
Comment by arecurrence 6 hours ago
They also have this comment in getting started: "Pin the CLI. This is not optional: a Claude Code update changes the harness, and a changed harness looks exactly like a changed model. Turn off auto-updates and write down the version you're pinning"
Comment by pythonaut_16 4 hours ago
Wild because as an end user I don't care what Anthropic changed to affect performance, I only care that Anthropic caused degraded performance.
Comment by Rapzid 3 hours ago
So your harness behavior can change without updating it.
Fun.
Comment by codegangsta 5 hours ago
The only thing I could maybe see is that any changes that are being made are happening on the subscription tiers on not the api tiers, but even that seems like quite a stretch.
Like anyone who is building agents with a good eval suite would know, models have been pretty consistent and even small harness changes can impact performance considerably.
Comment by antupis 5 hours ago
Comment by montroser 5 hours ago
Comment by velcrovan 9 hours ago
Comment by aerhardt 6 hours ago
Comment by sergiotapia 5 hours ago
He has his "nerfbench" he calls it. Very useful and entertaining at least. :)
Comment by morley 5 hours ago
Comment by jrflo 6 hours ago
Comment by nonethewiser 6 hours ago
If there was a silent degradation then the recent chatter about suspected nerfing is what you would expect to see. Of course that's not evidence, but I dont think we can say it's far more likely that its all subjective.
I mean the basic intuition doesn't seem unfouded. Maybe people can confirm/deny this contention for compute. But Anthropic is compute constrained. Inference takes compute. Model development takes compute. Isn't it plausible, and even likely, that there will be periods of contention? Would Opus 5.5 performance just silently get worse if they gave it less compute, as opposed to just being slower or something? Or do we have information that suggests inference compute is affected by model development?
Comment by pythonaut_16 4 hours ago
Anthropic has confirmed that they make changes to the models, for example with the recent update to limit reverse engineering.
Comment by jrflo 3 hours ago
[1] https://www.rensoart.com/why-your-eye-is-ahead-of-your-hand-...
Comment by WarmWash 5 hours ago
Comment by rzk 15 hours ago
https://www.reddit.com/r/ClaudeCode/comments/1xr9x5y/the_ner...
Comment by ozgung 9 hours ago
Comment by thousand_nights 6 hours ago
i've seen people on social media claiming all sorts of things about Fable 5.5, Opus 5.6 and Sol 6.2 and what-not for the past few weeks, but it just seems like engagement farming with no proof
Comment by DavCreator 15 hours ago
Comment by persedes 4 hours ago
Comment by wildmXranat 11 hours ago
Comment by ZiiS 5 hours ago
Comment by jessyco 11 hours ago
Comment by thatsabadlook 12 hours ago
Comment by lp92 10 hours ago
Comment by mapontosevenths 10 hours ago
Comment by UncleOxidant 6 hours ago
Comment by pwython 5 hours ago
Comment by gwerbin 9 hours ago
Comment by UncleOxidant 6 hours ago
Comment by mapontosevenths 5 hours ago
Flash Next is really great, but you still need pretty decent hardware. A DGX Spark, Strix Halo, or Mac with a lot of memory. You can use things like Strata to squeeze it into a system with only 32GB of VRAM by offloading a lot of it to system memory and still get something that "works", but the quality falls off a cliff too. At that point you get better results out of Qwen 3.8 27b in int4.
Never go below a four bit quant if you want good results. A worse quant of a bigger model is often easily beaten by the small model at decent quality. A lot of the people who think local AI suck think that because they don't understand that low quants == dumbass model. You aren't just compressing data, you're reducing the amount of compute it uses which effectively lowers it's IQ.
If you want to run something actually useful for cheap Qwen 3.8 27b on a 32GB GPU in int4 should be passable. It's more like Sonnet for a year ago. To match last years Opus you really need at least 128Gb.
Personally I have two Sparks connected with ConnectX 7. Now I can run GLM 5.3 locally at 30-40 tps and it's honestly been great. It really cut my dependence on cloud providers and I can run an abliterated version that never refuses my Cyber related tasks.
Comment by tyzoid 3 hours ago
Comment by mapontosevenths 2 hours ago
Folks like to think of 'weights' as just storage, but they aren't (except with stuff like engrams). Those digits of precision encode actual computation, not just storage. There is always a cost, it's lossy compression after all. It's like MP3 vs AAC. If you can't hear the difference it just means you haven't encountered it YET.
That's not to say that you ever will. The cost could be in weird far out edge cases, but whatever it once encoded... It's gone now and it ain't coming back.
Comment by 100111011111 6 hours ago
Comment by appletrotter 6 hours ago
Comment by boomskats 10 hours ago
Comment by xeshuman 10 hours ago
Comment by nozzlegear 7 hours ago
Comment by nekusar 11 hours ago
And with Strata running at 50tok/s on my desktop is all I need. Would I like faster? Sure! But it's super useful in all sorts of tasks now.
Comment by sumeno 4 hours ago
Comment by boomskats 10 hours ago
No longer am I constantly made to feel like Ingrid Bergman in that movie with all the lights.
Comment by benwills 15 hours ago
Tonight has been maddening with the kinds of absurd mistakes it's repeatedly making. It's so frustrating.
I'm the kind of person that wants something to be consistent and reliable. And Anthropic has been great, except for in this way. Which is enough of a recurring frustration (about every couple months this year) that I genuinely can't wait for other options to catch up. Then I'll be leaving as soon as I can.
I just don't know how long that will be.
Comment by jdcasale 15 hours ago
Totally possible that I'm just hallucinating/projecting/etc or my workflows somehow changed in terms of difficulty, but it's been kind of shocking.
Comment by cromka 15 hours ago
Now it's like talking to my hungover self, after 3 days bender, who just wanted to be left alone.
Comment by gitmagic 13 hours ago
Comment by Eddy_Viscosity2 11 hours ago
Comment by Roark66 15 hours ago
Comment by my-huge-pony 13 hours ago
And people wonder why open models are a big deal, and why some people love them so much, despite being 30% worse than the frontier.
Having control over something that writes most of your code is important.
Comment by jeffybefffy519 12 hours ago
Comment by jann 13 hours ago
Comment by EspressoGPT 9 hours ago
Comment by giwook 9 hours ago
"More reasoning" != "better"
Comment by matheusmoreira 12 hours ago
Only local AI capable hardware and frontier open weight models can provide that.
Comment by dr_dshiv 13 hours ago
Comment by fai5a1 13 hours ago
That's exactly why they did it. Nerf Opus 5.5, then drop Fable 5.5 just before IPO so it looks better next to its weaker predecessor.
Comment by bluerooibos 10 hours ago
Surely everyone is that kind of person.
Who wants to pay for a service that doesn't work properly half the time?
Comment by steve_taylor 13 hours ago
Comment by stavros 14 hours ago
Comment by aleqs 8 hours ago
Comment by tntpgh 11 hours ago
So I'm AI pilled and in another career, and started to think, what if the problem is the inputs? They release Opus X.X and at first it's a rush of their best users, best use cases, upgraded lanes. As weeks go on, adoption increases, cruft uses start to poison the model? Is this how the ongoing evolution works? I'd love to get Sonnet 5.5 and Opus for review in a place where I could reliably daily drive for X months / Y years etc.
Comment by smurf9852 1 hour ago
- They run A/B tests continually. Hence the "how is Claude doing: good/okay/bad" question.
- They try to shrink the model while keeping performance, using quants, etc. they keep the name though. Opus at the first, is often not the same Opus a month later.
- My friend works at a top 100 spender on Anthropic. He complained about nerfing to his point-of-contact at Anthropic, and they did some setting change and it didn't happen anymore.
- He, European, says the models can get worse around 4pm, which is when America gets to work
Comment by Klathmon 19 minutes ago
Every time I think about how this could happen it just feels like outright fraud. It can't be legal for a company to silently and intentionally give you a worse product, can it?
Comment by ngram 10 minutes ago
Comment by ricardobeat 15 hours ago
Opus is suddenly fumbling basic tool calls and failing to finish tasks even at high, where I had been permanently using it on low effort with success since it came out. It is very frustrating.
My guess is they quantized it and/or reallocated DC capacity to train a new model, this has happened before.
Comment by amelius 14 hours ago
Not just frustrating, it can also be dangerous. What if you trust Claude with certain security-sensitive things (because experience), and suddenly you cannot trust it anymore like that?
Comment by Azantys 12 hours ago
Comment by pythonaut_16 2 hours ago
Comment by criddell 12 hours ago
Comment by mring33621 4 hours ago
Comment by losvedir 9 hours ago
Comment by 4ggr0 13 hours ago
then $corp should remove your access to these security-sensitive things ;)
Comment by pakitan 13 hours ago
Comment by polishmijajca 11 hours ago
It is deterministic, if we're being pedantic
Comment by pakitan 8 hours ago
Comment by cyberclimb 11 hours ago
Comment by xeshuman 10 hours ago
Comment by cyberclimb 9 hours ago
Comment by iterance 7 hours ago
Comment by thereader12 8 hours ago
Comment by ACCount39 12 hours ago
Comment by wholinator2 12 hours ago
Comment by Phemist 14 hours ago
Comment by trvz 13 hours ago
Comment by infamouscow 5 hours ago
Comment by skywal_l 14 hours ago
Comment by ricardobeat 2 hours ago
Comment by bita_nidir 11 hours ago
Killing it's own shell, multiple, multiple times in the same session. I'm sure I saw a phrase "I did it again".
It's so shit that it must be damage control. The alternative is to limit usage and that'd affect the IPO even more.
Comment by marsven_422 11 hours ago
Comment by crnkofe 13 hours ago
Comment by Zambyte 14 hours ago
Comment by jesse_dot_id 14 hours ago
Comment by my-huge-pony 13 hours ago
This really depends on your infrastructure. In this case it all depends on your hardware, and there is no secret sauce, you can buy the same GPUs or better than the big players are using. Self-hostef GLM in our company is faster than any commercial model. Of course the hardware was not cheap, but completely manageable for a medium or large company.
Comment by gmueckl 12 hours ago
Comment by antiloper 9 hours ago
You can not buy an H100.
Comment by Zambyte 13 hours ago
As for faster, maybe? It depends on the metrics and what you're doing with it. If you mean TPS, no, I get much higher TPS and even faster TTFT on my local setup than frontier models. If you mean time to complete tasks... maybe. If you're throwing whole projects at it to vibecode, yeah, a frontier model will dump slop so fast it'll make your head spin. If you're doing actual methodical development, like doing spec-driven development and actually reading the specs before spinning off agents to implement them, rather than just having another agent review it and yolo, you'll find that frontier models don't really push the needle that much, and you'll be making high-quality projects.
Comment by jesse_dot_id 1 hour ago
Also, yes, I do need the capabilities beyond what can be reasonably achieved with local models because threat actors are also using frontier models.
Comment by jmkni 11 hours ago
Comment by whatarethembits 11 hours ago
Comment by xeshuman 10 hours ago
Comment by actionfromafar 11 hours ago
Comment by techmunky 6 hours ago
Comment by jatora 5 hours ago
Comment by jesse_dot_id 1 hour ago
Comment by julianlam 5 hours ago
Comment by enraged_camel 8 hours ago
Yes? If you're building anything reasonably complex, it is a ton of work to keep everything in your head so that different parts of the system work seamlessly and work you do in one area does not adversely affect another area.
Comment by iugtmkbdfil834 13 hours ago
Comment by wannabe_intelle 13 hours ago
Comment by gmueckl 12 hours ago
Comment by kuratkull 12 hours ago
Comment by gmueckl 12 hours ago
Comment by jatora 5 hours ago
Comment by terminalcommand 11 hours ago
Comment by gmueckl 11 hours ago
Comment by terminalcommand 10 hours ago
Comment by gatlin 9 hours ago
Comment by llm_nerd 11 hours ago
But the in a million years bit, even taken as rhetorical bombast, is of course silly. The difference between local models and the frontier models is ever shrinking. Extrapolating out and eventually, sooner rather than later, the difference is going to be a wash.
Unless all of the vendors stop progressing open local models, the future is clearly there. It's why I think AI is important and valuable, but also the current leaders have a dubious financial path forward.
Comment by redanddead 10 hours ago
He's pretending like there's any magic to claude or the others, there isn't
Comment by gatlin 9 hours ago
Comment by Paradigma11 9 hours ago
Comment by gatlin 3 hours ago
Comment by sarjann 14 hours ago
And that’s looking at a large model, to host the equivalent sized model as Opus 5.5 you’d need more than a single dgx spark. A fairer comparison would be to Open models hosted remotely or comparable weak models like Luna which you would get away with a $100 plan or less. That also doesn’t account for token prices continuing to go down for the same level of intelligence.
Comment by ShinyLeftPad 13 hours ago
Comment by grim_io 11 hours ago
But even if that was not true, the more important metric, cost per task, has definitely gone down.
Comment by azan_ 12 hours ago
Comment by JohnHaugeland 12 hours ago
a dgx spark could never
Comment by HighGoldstein 13 hours ago
Comment by Zambyte 11 hours ago
On the single r9700 I was able to run q2 with 4 slots of 256k, and I think it was about 40 - 50 GB of system memory offloading? Got about 60 - 80 TPS per slot depending on concurrent use. With the two r9700s we are running q3 with 4 slots of 256k, using about 100 GB of system memory offloading, with mtp enabled. Getting about 70 - 100 TPS now.
Comment by SXX 13 hours ago
There are plenty of ways to run ds flash and qwen flash on single cheap gpu, but speeds are quite bad or contex windows are small.
Comment by mickyngub 13 hours ago
Comment by my-huge-pony 12 hours ago
"Frontier" (closed) models are better by definition, but if frontier models were good enough for you half a year ago, open models are good enough now.
Comment by jatora 5 hours ago
"good enough" leaves so much on the table...and wastes so much of your time. I value my time and attention
Comment by trvz 13 hours ago
Comment by razemio 13 hours ago
Comment by brabel 11 hours ago
Comment by m4xp 9 hours ago
Comment by aleqs 8 hours ago
Comment by xboxnolifes 7 hours ago
Comment by aleqs 5 hours ago
Comment by xboxnolifes 1 hour ago
Comment by aleqs 17 minutes ago
Comment by thinkpad13 12 hours ago
Comment by user43928 14 hours ago
Comment by Zambyte 13 hours ago
Comment by user43928 13 hours ago
Personally I was forced to use only GPT-5.6 Sol at work instead of Opus 5.5, and it was so much worse.
Benchmarks that control for benchmaxxing indicate all open-weight models behind 5.6 Sol and roughly at the level of GPT-5.5.
And that's for the latest large ones, much less local Qwen 3.8 Flash Next.
I would regret such a downgrade.
Comment by JohnHaugeland 12 hours ago
Comment by DrProtic 12 hours ago
Comment by pluralmonad 11 hours ago
Comment by s4i 10 hours ago
Comment by chrisweekly 10 hours ago
Comment by DrProtic 7 hours ago
Comment by chrisweekly 7 hours ago
Comment by hgoel 8 hours ago
Comment by pluc 12 hours ago
Comment by matkoniecz 11 hours ago
which GPU?
also, so, 90 months of my subscription? And I also would need to buy new RAM and other parts of a computer?
Comment by stavros 13 hours ago
Comment by Zambyte 13 hours ago
By choice, maybe. New models release faster than every nine months. And, evidently, you won't be running nine months of some fixed meaning of "Opus 5.5". What that means changes over time, out of your control, and without ever even being officially told.
Comment by stavros 13 hours ago
Now, if GPUs didn't cost an arm and a leg, the economics would have been different.
Comment by throwawaytodey 13 hours ago
Comment by ariwilson 4 hours ago
Eval context: 30 bug fixes and features evaluated by tests the agent didn't see. Ran on Opus 5.5 at medium effort in Claude Code.
20 of the tasks were last run on Nov 1, twice each. Nov 1 solved 36/40, and today solved 19/20. Thinking tokens per task were 0.95x Nov 1’s and output tokens 0.97x. The one significant change was speed: median time to first token decreased from 3.0s to 1.7s.
Caveats: one run per task today, medium effort only.
Comment by marcalc 25 minutes ago
Comment by Retro_Dev 17 hours ago
> I noticed this too as did many others. Had to bump my default reasoning but it’s not the same. Seems to often happen before new model drops
I heard that Qwen4 was dropping some time soon, I wonder if Anthropic is trying to announce a new model immediately after Qwen4 - both for their IPO, and to kill the competition.
Comment by Gareth321 15 hours ago
Of all the reasons to look at local inference, this is the one which pushes me in that direction the most. I want to rely on a model for consistency in my workflows. If I wake up on Monday and suddenly it's refactoring things it built on Friday, that's a huge problem. That makes it unreliable.
Comment by yfontana 15 hours ago
Probably because those "nerfs" do not show on sites that track model performance over time. Sometimes Anthropic/OpenAI mess stuff up in their harness, but usually not in the models themselves.
Comment by xscott 15 hours ago
Comment by fastball 15 hours ago
Comment by timschmidt 15 hours ago
Comment by grey-area 15 hours ago
Comment by user43928 13 hours ago
In my own work I have not once noticed a degradation where I could have said with any certainty that it's not within usual deviation or me having a bad day.
Conspicuously the model seems to be especially dumb and annoying when I did not get a lot of sleep the previous night.
When OpenAI and Anthropic engineers post here on HN that they do not quantize models and silently replace checkpoints in the API, I believe them.
I saw nothing that convinced me the people who are constantly making these complaints don't just mistake any suboptimal result for changes in the model.
Comment by dugmartin 10 hours ago
Comment by kasey_junk 12 hours ago
Everyone really should keep a few tasks around that are indicative of the work they do and run them a few times with the same model and a few times across model families and when new models drop.
It’s extremely informative to see with your own eyes the variance that always exists. Even if you can’t afford statistical relevance it’s valuable.
Comment by taspeotis 12 hours ago
Comment by shikck200 15 hours ago
This is the #1 thing i HATE with LLMs. They are not predictable like a compiler is.
Comment by cromka 15 hours ago
Comment by jatora 5 hours ago
Comment by cogman10 3 hours ago
There is random input to make the models evaluate differently every time, but without that (or if you fix it) then the model will always give the same output with the same input.
There's no somehow to it, it's actually surprisingly hard to make a computer do something in a non-deterministic fashion.
Comment by KeplerBoy 15 hours ago
Comment by lukan 14 hours ago
Comment by monster_truck 15 hours ago
Comment by singularity2001 14 hours ago
Comment by techmunky 6 hours ago
Comment by singularity2001 2 hours ago
Comment by bmacho 14 hours ago
6 lines per model? Can't you put that 6 lines in a function/macro/decorator/library so you only have to call it?
Comment by monster_truck 14 hours ago
Comment by hgoel 8 hours ago
Comment by singularity2001 2 hours ago
Comment by axelthegerman 10 hours ago
To me it seems there should be a very viable middle ground of paying for open model hosting by a trusted provider - unless I'm only hearing from 24/7 vibe coders
Comment by prymitive 14 hours ago
Comment by driverdan 9 hours ago
Sounds like those teams need better leadership. Deterministic tools should always be used along side LLMs to improve the results and reduce costs.
Comment by Schiendelman 13 hours ago
If you have 99.9% already - that's better than any pre-LLM deterministic linter.
Comment by nonethewiser 5 hours ago
It's like saying "save this json as .txt but using valid json syntax." I mean maybe that will work most of the time but WHY?!
Comment by Festro 13 hours ago
Lots of "this is a potential issue, I didn't check into it though" which is super frustrating to see. The model just points out major flaws in logic or barriers but goes no further than a comment on it.
I've got a Qwen coder model and a flash next model locally now, so it's not the end of the world. But it does need to be remedied - are we seeing them prep for a new model deploy when this happens? Or are they experimenting with leaner hardware to drive down costs ahead of IPO?
Comment by danielfoster 13 hours ago
It does seem like Anthropic is experimenting with how much less they can offer users. I also get the feeling they are judging what resources a task deserves and dumbing things down accordingly. I’m seeing lazy responses and skipped steps more frequently for non-technical queries.
It’s definitely possible the average user hasn’t noticed, unfortunately.
Comment by throwa356262 11 hours ago
If you paid for X but are now receiving Y, you should be entitled to get your money back.
Every time I consider going back to Claude, I remember that mysterious week in February when Claude was failing to do even the simplest things. Things were so bad that BigPickle was correcting errors Sonnet was making.
And let's not forget the king of A/B testing here. Google has no issues breaking products for months just to test some ridiculous idea.These people should be publicly fired.
Comment by redanddead 10 hours ago
100% agree. I don't care how many reddit bots i see praising Claude, I bought max once wanting to see what the fuss was about, and the next day they broke the product and it was really embittering
Comment by e40 9 hours ago
Comment by throwa356262 7 hours ago
They can one day decide to rearrange the Gmail interface to absurd levels by removing the TO field or replacing everything with a big Gemini button. Then push it out without any internal testing to half of the planet, and suddenly you are doing IT support for grandma who is convinced North Korean spies have hacked into her email...
Comment by muddassirhq 5 hours ago
Comment by xscott 16 hours ago
Comment by beebmam 16 hours ago
Comment by digitalPhonix 16 hours ago
Comment by phyalow 15 hours ago
Comment by digitalPhonix 15 hours ago
Specifically
> YOU get to decide when the model changes
Comment by xyzsparetimexyz 16 hours ago
Comment by f6v 15 hours ago
Comment by Roark66 15 hours ago
I run it on a 6*rtx3090 consumer PC (no threadripper etc sadly) with very constrained pcie topology (4 cards sit on 2 lanes basically) and i still get 7k prefill and 50t/s single user or 200t/s 7 users. All at full 262k contexts of course and with 96GB of ram kv cache that means I can easily have 10+ Claude code sessions open with 1-7 generating at any time.
I've been the person that said, before opus 4.6 came out that this AI stuff is absolute crap for programming. Then it suddenly wasn't and I was using it many hours each day.
Local AI was the same. It was all crap. Models like GLM5.3 Flash that are many times larger than that qwen, lots of people are oooing and ahhing over I found way too inferior. Previous DeepSeek V4.1 Flash 0731 was atrocious. They benchmaxed it to hell, but at least it was small.
The current model of same name but release 1017 and double the size is currently the best open source model IMO. It even beats my self hosted Qwen3.8-flash-next.
I've tried hosting that DeepSeek model, but even adding another rtx3090 for a total of 7 cards and my 192gb of ram bought when it cost under $1000 I get only about 25t/s decode and few hundred prefill. That is far too slow for me to use.
But, I believe once this pyramid scheme of circular financing finally bursts there will be a glut of hardware on the market where people like me will be able to buy equipment to run 750B models like we now run 120B.
Comment by pianopatrick 5 hours ago
Comment by Sphax 14 hours ago
Also, how much power does that consume at full tilt ?
Comment by DeSinc 14 hours ago
Truly insane times
Comment by Tepix 14 hours ago
That's around 1% of the price of 8x B200. At current prices, it's as low as $6200. At last year's prices that's $3700 or so.
Comment by sznio 10 hours ago
Comment by ghoul2 16 hours ago
Comment by gherkinnn 14 hours ago
Comment by ImageXav 13 hours ago
Comment by EspressoGPT 7 hours ago
Comment by IshKebab 13 hours ago
Comment by fooker 13 hours ago
I'm so happy to not look at bogus jargon that Claude made up.
Comment by Schiendelman 13 hours ago
Comment by senderista 7 hours ago
Comment by iugtmkbdfil834 13 hours ago
Comment by oh_no 10 hours ago
Comment by lukax 15 hours ago
Comment by Rapzid 13 hours ago
Under load requests queue and take longer.
Comment by nonethewiser 5 hours ago
However, how would less compute result in degraded performance as opposed to more latency? Like is amount of compute something you can actually tune to control for latency? Wouldn't that imply they are actually serving requests in other models? If I run a very large model locally on a shit computer vs. something maxed out, it's the latency that differs.
Comment by Rapzid 4 hours ago
They basically dynamically allocate compute into this pool from the general pool to meet demand and SLAs. If demand for priority processing spikes latency in the general pool spikes.
Almost all subscriptions use general pool. That's why it gets really slow sometimes. Unless you use "fast" which acts like priority processing and is super expensive.
So that's part of how they balance compute based on demand and fund the "excess" capacity. This is a bit reductive and basic, but it's all the usual Cloud on demand, reserved, and spot capacity techniques at play.
Comment by nonethewiser 3 hours ago
Im asking on how lower compute could translate to worse model performance. That's the implicit claim being made when people are saying Anthropic nerfs a model (result is bad, not necessarily slow). The only way I can think that could happen is if they actually swapped Opus 5.5 out for a worse model that takes less resources to do inference.
Comment by Rapzid 3 hours ago
There is no proof, the frontier labs deny it, and certainly it's not happening on hosts like Azure, Amazon, and etc.. The claim is that it's "trivial" to detect observation, so they serve the normal model if you try to measure it..
Basically the conspricy theory is:
* OpenAI/Anthropic nerf their models regularly to reduce compute demand
* It's impossible to measure and thus prove
Comment by cma 13 hours ago
TPUs only made up a small percentage of the fleet, but, exacerbating that bug, if you got routed to a TPU instance at some point in your chat then another bug kept you routed there for the remainder of the chat.
The second one I'm aware of is earlier in 2026 they decided to save usage by stripping out all thinking tokens if you left your chat idle for one hour (cache timeout) and then came back to it, causing massive model performance degradations. This one also made me very skeptical of Chinese distillation, until the reports of how you could use Haiku to extract the raw reasoning of the larger models.
They fixed that, but recently they switched to doing auto-compactions for long running chats in anticipation of them going stale in cache. I think that one is usually what you want anyway and there is at least a way to recover to the uncompacted chat if you really need it, but it might also be a source of some degradation people are seeing now.
Comment by Rapzid 6 hours ago
But the model NERF conspiracies are bunk.
Comment by cma 3 hours ago
But the harness one was not just a random harness regression; they were getting a huge influx of users and pretty clearly did it to save capacity. Not a great thing when you might be relying on attention to those thinking traces to reduce the risk of prompt injection etc. and it could have gone beyond major task degradation into a safety/security issue.
Comment by Rapzid 3 hours ago
Through the lens of a conspiracy theory this could be viewed narrowly as "cheating" their users to reduce load.
But there are other motivations for the constant work going on in the harnesses that paint a fuller picture.
Comment by aurad 14 hours ago
Weirdly enough, Sonnet quality seems unchanged.
Comment by jarym 14 hours ago
You rewarded Anthropic's failure with more dollar spend. I get why you did it but...
Comment by basilgohar 11 hours ago
I don't have measured data aside from myself noticing my frustration level with Claude jumping on these days frequently over the past several months.
Comment by Aboutplants 1 hour ago
Comment by chr15m 1 hour ago
https://www.businessinsider.com/apple-batterygate-500m-lawsu...
Comment by mehdizare 1 hour ago
Comment by jascha_eng 6 hours ago
Comment by ironworks 2 hours ago
Comment by cube00 12 hours ago
The Windows Insider program has shown plenty of people will willingly sign up to be testers for a taste of the rawhide. Anthropic could do this in a transparent way but they continue to choose not too.
Comment by roncesvalles 10 hours ago
Pretty much the only alternative is loading up some credits and using Fable.
Comment by hetspookjee 9 hours ago
Comment by timcobb 9 hours ago
Comment by KerrAvon 6 hours ago
Comment by alexjplant 9 hours ago
A neutral third party who runs a matrix of closed-source coding benchmarks across multiple harnesses would be helpful but that'd take a lot of time and money...
Comment by Espressosaurus 6 hours ago
Both get the job done these days. I still hate Opus 5.5’s output, 6.1 Sol does an acceptable job of doing a second cleanup pass to it.
Comment by ModernMech 9 hours ago
Comment by Betelbuddy 9 hours ago
1)- Get a coding task and get the output of Opus and Astra.
2)- Open a new session and ask each other to review in detail the solution from the other model without mentioning where is it coming from.
3)- After the review, ask the original model to comment on it and state which solution is better and if the criticisms are valid...all in a new session.
4)- At the end Opus and others from Anthropic always end up agreeing the OpenAI model solution is better. My human review agrees.
After doing this for a few weeks...and consistently having their models rating higher the OpenAI solutions...I cancelled the Anthropic subscription...
Comment by mnicky 5 hours ago
Comment by aleqs 9 hours ago
DeepSeek, Qwen.
Comment by nickalaso 5 hours ago
I tried $20 of usage credits as a test once the limit was reached.
I shit you not, it lasted for less than 5 minutes.
Comment by aleqs 5 hours ago
I get 5x more done (of equivalent quality) on my opencode go + DeepSeek flash sub for $40, than $200 anthropic sub.
Comment by nickalaso 5 hours ago
I have been using DeepSeek flash for a few projects and it is actually crazy capable, And I don't think I have spent $20 via api in a month yet.
Comment by aleqs 4 hours ago
Comment by nickalaso 3 hours ago
Comment by phoghed 3 hours ago
Comment by lp92 10 hours ago
Comment by altcognito 10 hours ago
Comment by WarmWash 8 hours ago
A bit like "You can order the steak for $75, or you can have whatever the chef is making for $30"
Comment by Tostino 11 hours ago
I don't think that's an excuse, but it is likely the reasoning.
Comment by NullifyNAN 7 hours ago
Comment by richardlblair 10 hours ago
Comment by bothers 9 hours ago
Comment by boxed 10 hours ago
Comment by pennomi 10 hours ago
Comment by boxed 9 hours ago
Comment by dang 6 hours ago
Comment by pennomi 5 hours ago
The model itself should not be substituted(for example, quantized) without an explicit SKU change.
Comment by nozzlegear 7 hours ago
Comment by Haven880 13 hours ago
Comment by jarym 14 hours ago
After I figured out, like this chap on X, that it wasn't ME, I diversified my model usage and now a lot more work has shifted to Astra/Sol and I'm learning to make my workflows more resistant to the whims of each model.
Comment by mstaoru 12 hours ago
I run a small local GPU cluster for Qwen 3.8 Flash and while it's "free" (you should check electricity prices in EU...) unfortunately it doesn't even compare to Opus 5.5 or Astra in capabilities. It's like GPT 6 vs GPT ~4, but imagine GPT 4 is also 100x slower and sounds like an airplane taking off.
In the end it's totally possible that I would pay more for electricity running Qwen for 24 hours churning on some complex problem vs. Astra one-shotting it in 15 minutes.
I hope we get there, but it's not there yet, and I'm sure never will be with consumer GPUs. Maybe if you spend $20k+ on a local AI rig. There's just no market force to give access to AI to everyone at fair price.
Comment by DavCreator 15 hours ago
Comment by Scene_Cast2 4 hours ago
If you look at any sort of tracker, there's no telling whether you're in the same experiment group as the tracker (most likely not).
Comment by nickalaso 3 hours ago
Comment by terminalcommand 16 hours ago
Comment by d3ckard 5 hours ago
Comment by drknownuffin 5 hours ago
Comment by nico 4 hours ago
Comment by jostmey 5 hours ago
Exactly the reason I had previously cancelled my openai subscription
I'm looking into Gemini
Comment by orbital-decay 13 hours ago
Comment by purpleidea 6 hours ago
Comment by JeppyG 4 hours ago
Comment by xbmcuser 15 hours ago
Comment by steve_adams_86 9 hours ago
I’m only prototyping so most of the code will be discarded, but even in this circumstances you can’t allow too much sprawl and decoherence within a single project. It makes prototyping cost so much more over time. It was pretty frustrating.
Comment by contubernio 5 hours ago
Comment by PostOnce 14 hours ago
Comment by __natty__ 13 hours ago
Comment by jonathanlydall 15 hours ago
I wouldn't say I've especially noticed its effectiveness having been reduced, it's just slower.
Comment by dang 6 hours ago
Livenerf: Has Opus 5.5 been nerfed yet? - https://news.ycombinator.com/item?id=49901736 - Sept 2026 (394 comments)
Comment by jatora 5 hours ago
Variable token usage? Sure. To be expected in non-deterministic systems like these.
Distinct increase in errors and issues? Never. Not within a single model's lifespan have I ever experienced this.
And this whole notion of the A/B testing of performance/usage is completely ridiculous. There is zero evidence it has anything to do with performance. There are a trillion things to A/B test besides things that hamstring groups of users, so this is just being used to confirm the bias of people already caught up in these "theories."
I await any realistic indication.
Comment by wat10000 4 hours ago
If they're messing with models like this, surely they'd at least occasionally make a tweak that improves intelligence rather than degrading it. But I never see anyone say Model 4.2 got smarter a week ago or whatever.
Comment by shambu2k 3 hours ago
Comment by yash-kapoor 2 hours ago
Comment by 0xb0565e486 5 hours ago
On some long running conversations it seems to better understand the end goal, follow the constraints we have established.
Comment by bryzaguy 4 hours ago
Comment by Asmod4n 15 hours ago
Comment by rzk 9 hours ago
Comment by sandos 7 hours ago
Comment by setnone 14 hours ago
Comment by tammyselvi 15 hours ago
Comment by cromka 15 hours ago
Comment by Surac 11 hours ago
Comment by senderista 5 hours ago
Comment by ptrwis 8 hours ago
Comment by closetheloopdev 13 hours ago
Comment by vlyan 13 hours ago
2) the wholesome party is not in power yet
3) even when they are, the orange man will veto everything they might attempt to do
4) even when the orange man is replaced with someone wholesome, and that wholesome person enacts a bunch of wholesome legislations, data centers will simply move literally anywhere else on Earth.
Comment by closetheloopdev 12 hours ago
Comment by Schiendelman 13 hours ago
Comment by vlyan 12 hours ago
>In Ohio alone, at least 14 municipalities passed bans or restrictions on datacenter development, including in Sunbury, where Amazon has proposed a $2bn datacenter project. In Maine, eight municipalities passed temporary datacenter moratoriums. In Emporia, Kansas, where a 1,000-acre gigawatt-scale datacenter was recently proposed, a ban on high-impact datacenters was approved by voters.
and now they will be built elsewhere.
I think there's a rather obvious precedent for that inevitable outcome.
Comment by partarstu 8 hours ago
Comment by sunaookami 16 hours ago
Comment by kolinko 16 hours ago
Comment by throwaw12 15 hours ago
* nerf them based on supply and demand, when you have a high demand, nerf it, but keep charging same price.
* do you want to show revenue growth to investors? increase thinking tokens, customers will keep paying, because again, this is non-deterministic system, sometimes it thinks more
* do you want to increase profits? start serving 4-bit, 5-bit quantizations and keep charging same price
* want even more? publish a paper "Advanced Auto Super Smart Prompt Router - AASSPiRation", and start routing requests to Qwen3.8-27B or GemmaE2B from time to time on the edge
* Not enough? introduce "Complex Chained Workflows - CCW" in your coding harness, which spawns multiple deterministic workflows (which you can't stop or control) and they will use Haiku to write the code, then use Opus 5.5 high to verify the code (which is obviously wrong) and Opus 5.5 produces recommendations on how to fix the code, delegates to Haiku, which again fails writing proper code, and keep doing it 5-6 times, you made lots and lots of money (don't forget, all should run in parallel, to pick one best result among 10 outputs).
Comment by Schiendelman 13 hours ago
Comment by throwaw12 11 hours ago
How do you even lower the quality - serve half broken car for a luxury order? No way person who orders luxury car accepts it.
Or do you increase wait times? - sure, order gets cancelled, you won't get a payment for that.
There are of course ways, but you still can do something, in case of LLMs, you blame yourself for poor prompting and retry, which again makes money to LLM providers
Comment by kube-system 3 hours ago
Comment by Schiendelman 9 hours ago
- You can lower the quality standard of which car counts as which class. There are many classes of vehicle on both platforms.
- You can delete or not consider low ratings from certain users. Both companies do this already.
- You can increase wait times, of course. It doesn't at all follow that the order gets cancelled. It depends on the market and what each company believes the other is doing.
That's thirty seconds of brainstorming.
Comment by peri-cl 15 hours ago
I have no doubt they will ensure their users get an accurate picture of Opus 5.5 within hours.
Comment by MallocVoidstar 14 hours ago
Comment by peri-cl 14 hours ago
The purpose of AI benchmarking is to inform people making large spending decisions what alternatives are available to them.
I *do* wish we wouldn't let software companies call this "A/B testing". That's not what that term means to a typical reader. In any other market than software, you'd call it something like "misleading consumers in respect to product composition" and "an unfair commercial practice". That's language from the EU "dual quality" food scandal, which saw food brands (Coca-Cola was one) adulterate their recipes to use cheaper ingredients in select markets—though the external packaging was kept the same.
https://ec.europa.eu/commission/presscorner/detail/en/qanda_...
(I suppose Coca-Cola's CEO would prefer we talk about what they did as "A/B testing").
Comment by dstu 14 hours ago
Comment by Exoristos 3 hours ago
Comment by telaandrews2 50 minutes ago
Comment by greenowl 5 hours ago
Comment by skylurk 14 hours ago
Comment by MisterMunchkin 5 hours ago
I just don’t see the point of using these expensive models anymore.
Comment by Cthulhu_ 14 hours ago
I'm reminded of the video game industry where they would launch a game without any in-game purchases at launch, get the reviews to make note of it and give it a higher rating because of it... then add in-game purchases anyway. I think that stopped again though.
Comment by robinduckett 12 hours ago
Comment by butlike 7 hours ago
Comment by walthamstow 13 hours ago
If they did, there's no way that remains a secret.
If they didn't, Anthropic would be making their own service noticeably shitter than AWS Bedrock
Comment by tarpump 2 hours ago
Comment by hoppp 6 hours ago
Comment by 0x70dd 14 hours ago
Comment by seqizz 13 hours ago
Oh, even psychological effect would be nice if you slightly tune down the current frontier 1-2 weeks before releasing the new one.
Comment by Northernator11 3 hours ago
Comment by Topfi 12 hours ago
Sounds like analysis fully driven by a model, which can be fine, if you know what you are getting into and can verify the output. Just last week had someone ask Claude Opus 5.5 on High about watermarking after I informed him and he'd rather believe a models output over me, do a basic Google search or spend the effort reading Anthropics communications on the matter.
The model told him with no uncertainty that watermarking text was not implemented in any Anthropic models, whereupon he showed me and I then asked him to just ask the model to check again, ideally online. These models do still "hallucinate", they still have major gaps in their output not easily caught if you don't know the topic and interestingly, anything connected to LLMs, model providers, etc. tends to be where they do worst.
The annoying thing is, they still sound immensely authoritative across most any topic, but especially LLM stuff, which is such an easy way to get tricked. I have been for sure in the past and will be in the future, it's why I recommend having some incredibly niche hobby (like sewing with less known materials, obscure motorcycles, etc.) to check how quickly the model makes a mistake which no one in the know would make. Just to keep yourself disillusioned and inoculated.
In this case, looks like the LLM did not consider that these are (and have been for months now) just summaries and the actual reasoning can not be analyzed for encryption reasons.
If in doubt, please do some research independent of the model output. LLMs not having any internal "understanding" that'd give them anything akin to an internalized "feel" for what they "know" accurately enough is one of their major flaws.
Funnily enough, once did the opposite, made a manual analysis of a Github outage, then had the model just write an artifact to quickly share. Was lazy, could have just put something on Pages, but taking summary changes and extrapolating that to a "nerf" is less ideal.
On the regression front, I run my own, private evals and have only once encountered consistently reproducible, over run-to-run deviation, degraded performance, which was purely present when using Claude Opus 4.8 in April after some system prompt changes in Claude Code specifically which were addressed soon thereafter. These were not present with OpenCode via API and any other time the public on Reddit and co. reported regressions, I could not reproduce it, even when using Claude Code as the harness and a subscription.
What I have encountered and been able to reliably reproduce is that certain labs do very clear teach to the public benchmarks and underperform them commonly, whereas others do not. And that certain, especially cheaper and higher throughput, neoclouds very clearly take some quality affecting, tool call misformatting shortcuts.
For what it's worth, currently measuring, but haven't seen anything so far with Opus 5.5, especially nothing connected to reasoning that'd make the assessments some of the commenters draw from this apparent.
Comment by antiloper 9 hours ago
Comment by r_lee 13 hours ago
Comment by deniska 12 hours ago
Comment by igleria 15 hours ago
That would be the less bad reason.
Comment by listedb 16 hours ago
Comment by etcetcetcetceta 15 hours ago
Comment by tallesborges92 11 hours ago
Comment by dyauspitr 3 hours ago
Comment by PUSH_AX 15 hours ago
Comment by andai 13 hours ago
Comment by hoppp 9 hours ago
Comment by anonzzzies 14 hours ago
Comment by hebelehubele 16 hours ago
Comment by rskeens 11 hours ago
Comment by j45 4 hours ago
Comment by amelius 14 hours ago
Comment by jwpapi 13 hours ago
Comment by perks_12 15 hours ago
Comment by putlake 5 hours ago
Comment by ex1fm3ta 4 hours ago
Comment by lifeisloving 5 hours ago
At the model release people become high/manic/addicted to the newest model think they now have some new superpower and then that "high" wears off and you think the model isnt as impressive.
The truth is llms have a slot machine-esque UX to them, and the labs designed it this way.
Dont worry you'll get your new model with some mystical name any day now and a month or two afterwards you'll be posting about how it no longer feels as good to use.
Comment by zombot 10 hours ago
Comment by tsukikage 15 hours ago
Comment by overflowy 15 hours ago
Comment by musha68k 15 hours ago
Comment by eithed 15 hours ago
I wonder as well whether would this pop up on nerfbench
Comment by kasey_junk 12 hours ago
Comment by katravathpavank 4 hours ago
Comment by cft 12 hours ago
I'm afraid to have touch my code base because a nerfed model could slip in stupid bugs.
This is also why a weaker local model might be preferable because it allows me to calibrate trust, and my expectations don't change.
I have had Astra analyze my long running Opus conversations and the degradation definitely happened on November 6th and 7th.
Comment by gib444 14 hours ago
Comment by tehjoker 1 hour ago
Comment by bita_nidir 12 hours ago
Instead of being Opus on high (effort), it's Opus is high.
Comment by Giorgi 16 hours ago
Comment by hugodan 14 hours ago
Comment by davidd_1004 15 hours ago
Comment by smrtinsert 6 hours ago
Comment by thewhitetulip 12 hours ago
I use Sonnet 5.5 daily and Opus rarely. My usage is also a little involved as in I do all the design and strategy and get Sonnet to just write the code
For that, Sonnet has been consistent
I use Opus or Fable when it's a dumpster fire situation where we have no time to think even
So far I've never had an issue with Sonnet even.
Comment by BiteCode_dev 13 hours ago
Dude, you have a mythical creature at your disposal at retail, chill, it's going to be ok.
Comment by JohnHaugeland 12 hours ago
all the measurements always say it isn’t
anyone who grew up playing dungeons and dragons gets that this is just people saying “you don’t understand, these five used to roll high”
every llm space is inundated with rank amateurs explaining at great length how it used to be better yesterday
nobody has the courage to clean out the obvious bullshit, so the drone gets ever louder and the signal gets ever rarer
do you remember what programming was two years ago?
stop complaining so much
Comment by Madmallard 14 hours ago
This company does not deserve to be successful and has no moral high-ground.
Comment by geberele 1 hour ago
Comment by blovett80 5 hours ago
Comment by taioladipupo 9 hours ago
Comment by vaahiiid 5 hours ago
Comment by aryanthakor 10 hours ago
Comment by FastDeep 15 hours ago
Comment by redanddead 10 hours ago
Comment by 486sx33 12 hours ago
Comment by 1STORM3 14 hours ago
Comment by iamlaslo 10 hours ago
Comment by squidmaster 13 hours ago
Comment by bandrami 14 hours ago
Comment by antihipocrat 11 hours ago
Comment by novoreorx 14 hours ago
Comment by fractalf 14 hours ago
Comment by twobitshifter 11 hours ago
Comment by giwook 9 hours ago
Comment by WarmWash 8 hours ago
Comment by margalabargala 9 hours ago
Comment by giwook 7 hours ago
How are they making money in your view?
Comment by margalabargala 6 hours ago
What you said doesn't yield any information whatsoever about whether or not subscriptions are profitable, all that says is that subscriptions are less profitable than API.
Things are able to be less profitable than other things while still being profitable.
If something like the API is very very profitable, it's even possible for profitable things to be much less profitable!
Comment by Toynbeeidea 9 hours ago
Comment by margalabargala 8 hours ago