512GB Mac Studio

Posted by immutlex 1 day ago

Counter44Comment50OpenOriginal

Comments

Comment by gnabgib 1 day ago

Dupe/Discussion (67 points, 1 week ago, 82 comments) https://news.ycombinator.com/item?id=50277166

Comment by WarOnPrivacy 1 day ago

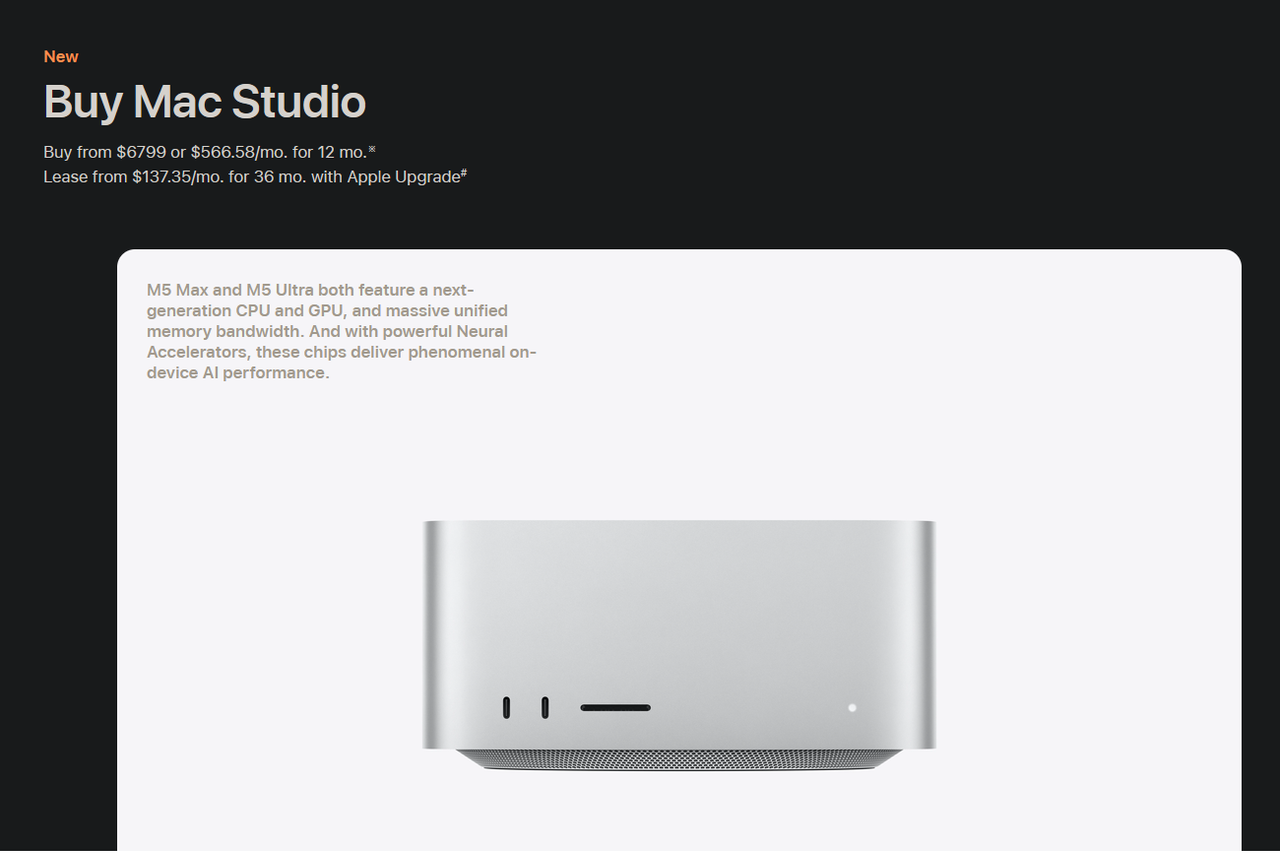
When the page first loads, it shows a different price for ~1sec. It quickly overwrites that and displays the much larger, eye watering figure.

1st load ref: https://i.postimg.cc/YC5V5yZH/prerewrite.png
Comment by tomschwiha 1 day ago

That's the 96GB ram price.

Comment by aappleby 1 day ago

what the f is that sketchy site doing?

Comment by simonh 1 day ago

Loading the page with default parameters, probably from cache, then applying the specified parameters

Comment by ChrisRR 1 day ago

The state of the web when every site that is just text and images, for some reason uses javascript

Comment by immutlex 1 day ago

Has any individual/SMB purchased this yet? Aware the ROI isn't there for most individuals that don't heavily use LLM for coding or multi agentic workflows -- but for those that it does make sense this is ~$68k cheaper than the next alternative making this the most realistic option for consumer grade access to frontier models.

Specifically interested if anyone has ran GLM-5.3 (753B MoE) in 4-bit on a 512GB Mac Studio. Looking for real world usage numbers and/or any benchmarks you might have performed.

Thanks!

Comment by nsagent 1 day ago

They haven't shipped yet (people who purchased the moment it became available have delivery dates near the end of the month). That said you can estimate it's speed by looking at the 256GB version for models with similar numbers of active parameters (GLM 5.3 has 40B active parameters). So for 4-bit you could compare to what people are getting Qwen3.8 27B at 8-bit (which is around 2000 tok/s prefill and 70-80tok/s token generation [1]). It might be a little higher or a little lower due to the different architecture and kernel optimizations.

[1]: https://omlx.ai/benchmarks/performance?model=qwen3.8+27b&chi...

Comment by bigyabai 1 day ago

GLM-5.3 would be bottlenecked by the M5's GPU, here. I don't have any hard numbers, but Apple Silicon is known for weak prefill performance on larger models (yes, even MoEs).

Comment by evanjrowley 1 day ago

Good to know. Private GLM-5.3 is really the one use-case I can imagine for a system like this - It does very well with cybersecurity tasks, which are either blocked for most people by current providers, or on their way to getting blocked based on the regulatory/political trends. Such a capability could become very valuable when supply becomes artificially limited, although I expect the Chinese labs will be the last hold-outs. Imagine not being able to do security hardening on your own tech because government-imposed guardrails decide your legitimate prompts appear "risky". In such a world, what would an unconstrained cyber-capable model be worth?

Comment by cromka 1 day ago

I think 2xGB10 might be a better option but don't quote me on that.

Comment by pmarreck 1 day ago

is this a hardware or software limitation?

Comment by bigyabai 1 day ago

Both. Apple Silicon could have the best of both worlds if it supported dGPU/eGPU tech, but Apple depreciated that about a decade ago. So you're stuck with fast RAM and a slow GPU.

Comment by Tepix 1 day ago

Crescent island will be cheaper and might ship earlier. It could also be faster.

Comment by drsalt 1 day ago

apple always charged ridiculous numbers for ram and disk space.

Comment by jpitz 1 day ago

What are you comparing this to, and for how much, and what sort of benchmark numbers is it getting? I'd love to run better cheaper hardware. I'll gladly pay you a reasonable finders fee.

Comment by frr149 1 day ago

The elephant in the room: how much of those 512 Gb is usable by the GPU?

Comment by sithadmin 1 day ago

75% by default, ~90% with manual overrides.

Comment by jonplackett 1 day ago

You can get it up to 29k with max storage.

Comment by DerekL 1 day ago

By comparison, the Macintosh IIfx with 4 MB of memory and a 160 MB hard disk was about $28k in today's dollars.

https://en.wikipedia.org/wiki/Macintosh_IIfx#Models

Comment by tencentshill 23 hours ago

So, effectively just as worth it for those who need it.

Comment by vr46 1 day ago

It was a 10k starting price in the UK IIRC, there were two in our maths department!

Comment by vic20forever 1 day ago

I remember reading about the Apple Lisa when it was announced. Launched January 19, 1983, with 1 MB RAM: $9995

https://en.wikipedia.org/wiki/Apple_Lisa

Comment by evanjrowley 1 day ago

All roughly the same price, for a consumer who has won the lottery: - 1x 512 GB Mac Studio with the 4 TB disk storage option. - 4x Nvidia GB10s (total 512 GB RAM) each connected with a 100 GiB/s link to a Mikrotik CRS504-4XQ-IN. - 3x Ryzen AI Max+ 495 192GB systems (total 576 GB RAM), connected via a 40 GiB/s link directly to each other.

Comment by TheHalfDeafChef 1 day ago

Your AI Max+ 495 would be bottlenecked by ~300gb/s no?

Comment by mrheosuper 1 day ago

What is the 40GiB link ?

Comment by SomeHacker44 1 day ago

Probably USB4.

Comment by mrheosuper 1 day ago

Well USB4/TB4 is 40 Gigabit/s, so 8 times slower than what they are expecting.

Comment by simonh 1 day ago

Does anybody actually expect bandwidth to be expressed in bytes, rather than bits?

Comment by TheHalfDeafChef 1 day ago

Your AI Max+ 495 would be hobbled by ~300gb/s bus no? So muuuuch slow inference

Comment by mannyv 1 day ago

Ship date is 3/5/27 for the 512GB model.

Oddly enough, Apple Upgrade isn't an option.

Comment by tonyedgecombe 1 day ago

5/3/27 if you are in the UK.

Comment by ChrisRR 1 day ago

5/3/27 if you're in one of the ~150 countries that use date first

27/5/3 if you're in one of the ~15 countries that use year first

5/3/27 If you're in the 3 countries that use month first

Comment by hnfong 1 day ago

Guys let's all be reasonable and write the date normally:

2003-05-27

Thanks.

Comment by simonh 1 day ago

ISO is the way to go.

Comment by mannyv 23 hours ago

I usually write it 2026-Mar-03 in email these days because you never know which locale people are in.

Comment by vr46 1 day ago

Will one be enough, is my only question?

Comment by osti 1 day ago

To be safe, just buy four and you'd be able to run the current biggest open weight models.

Comment by vivzkestrel 1 day ago

- gonna ask you HN smart folks a deep question

- one one hand, the 8GB RAM Mac mini with M6 as cheap as it maybe is an absolute waste of money when it comes to running LLMs

- on the other hand the most expensive machine is right here

- what is the cheapest most expensive machine you can buy capable of providing you the best ROI for running LLMs locally?

Comment by 1 day ago

Comment by justauserid 1 day ago

Get a personal computer with 48-64 GB RAM (or maybe even 32 GB). Whenever your model usages go beyond that – there's those APIs/subscriptions just for that. You are golden for most (really most) of the work.

But if your use-cases need extremely heavy-duty local models then just open your bank vaults and get the one you need.

Comment by paxy 1 day ago

Can't really answer that without knowing your use case. What is the largest model you need to run? What are you going to do with it? What tps do you need?

For just trying out local models and running occasional queries a 16GB mac will run an 8B-20B dense quantized model just fine.

If you are running at the scale of OpenAI then a data center full of blackwells will have the best ROI.

Comment by vivzkestrel 1 day ago

the use case is getting the best bang for your back per dollar

take an 8 year life cycle for all machines and think of the cheapest expensive machine that you can buy which ll give you a decent llm to run

Comment by simonh 1 day ago

Cheapest expensive? I'd say the M5 Pro Mini with 64GB RAM. That's certainly not cheap, but not ludicrous, and fairly capable. An M6 mini with 32GB would be the budget option and quite limited, you'd probably want to replace it after say 4 years.

To do significantly better than that with a Studio, say M5 Max with 128GB would cost twice as much again. It would probably be more than twice as performant and much more capable, but you'd be getting into very big bucks that IMHO would only be justifiable for paying pro work.

Comment by mjsweet 1 day ago

I recently bought the M5 Pro Mini with 64 GB of RAM, and it feels excellent. It matches the Max in CPU performance while running Qwen 3.8 27b. Although it is slow, I can complete tasks at what I would call Opus 4.6–4.8 levels. What surprises me is using Claude Code on it. The speed of building with that harness and testing iOS apps is impressive… full end-to-end control of Xcode through to TestFlight. This is a major upgrade from my old M1 Pro MBP.

Comment by hebetude 1 day ago

Buy one of the 128gb m4 max when people sell them to buy m5 ultras. It runs fine on the 27b models and qwen3.8 can actually run tools and perform tasks well. I use it for private agents, voice processing (no elevenlabs criminal pricing) and some photo manipulation though it's not very efficient at this task.

Comment by illusive4080 1 day ago

Probably 64GB MacBook Pro and run a 27B model on it comfortably.

Comment by Naru41 1 day ago

I hate to sound like Sam Altman, but is there actually any point in having 512 GB of RAM other than just pure tech hoarding?

Comment by Philpax 1 day ago

Running inference on LLMs that can fit in 512GB. For example, you would be able to run either GLM-5.3-Flash or DeepSeek V4.1 Flash 1017 on this, both of which are very respectable models. It's up to you, of course, if ultimate privacy is worth $25k.

Comment by _blk 1 day ago

... Or even 640K

Comment by Frost1x 1 day ago

512 ‘ought to be enough

Comment by rugberrydave 1 day ago

[flagged]